blueDelta manual
Compares two versioned lab run manifests, excludes only the candidates ruled out by an explicit dependency rule, and — given a test catalog — recommends the cheapest experiment that would separate what's left.
Is: Manifest diff and candidate minimization.
Is not: Never claims a surviving candidate caused the result, never runs an experiment or controls an instrument, and never infers from data the manifests don't contain.
Lab and research-integrity reviewers.
From the product's own repository:
make dev
make test
This runs entirely offline against synthetic fixtures and exits non-zero on any mismatch. It does not connect to any production data source.
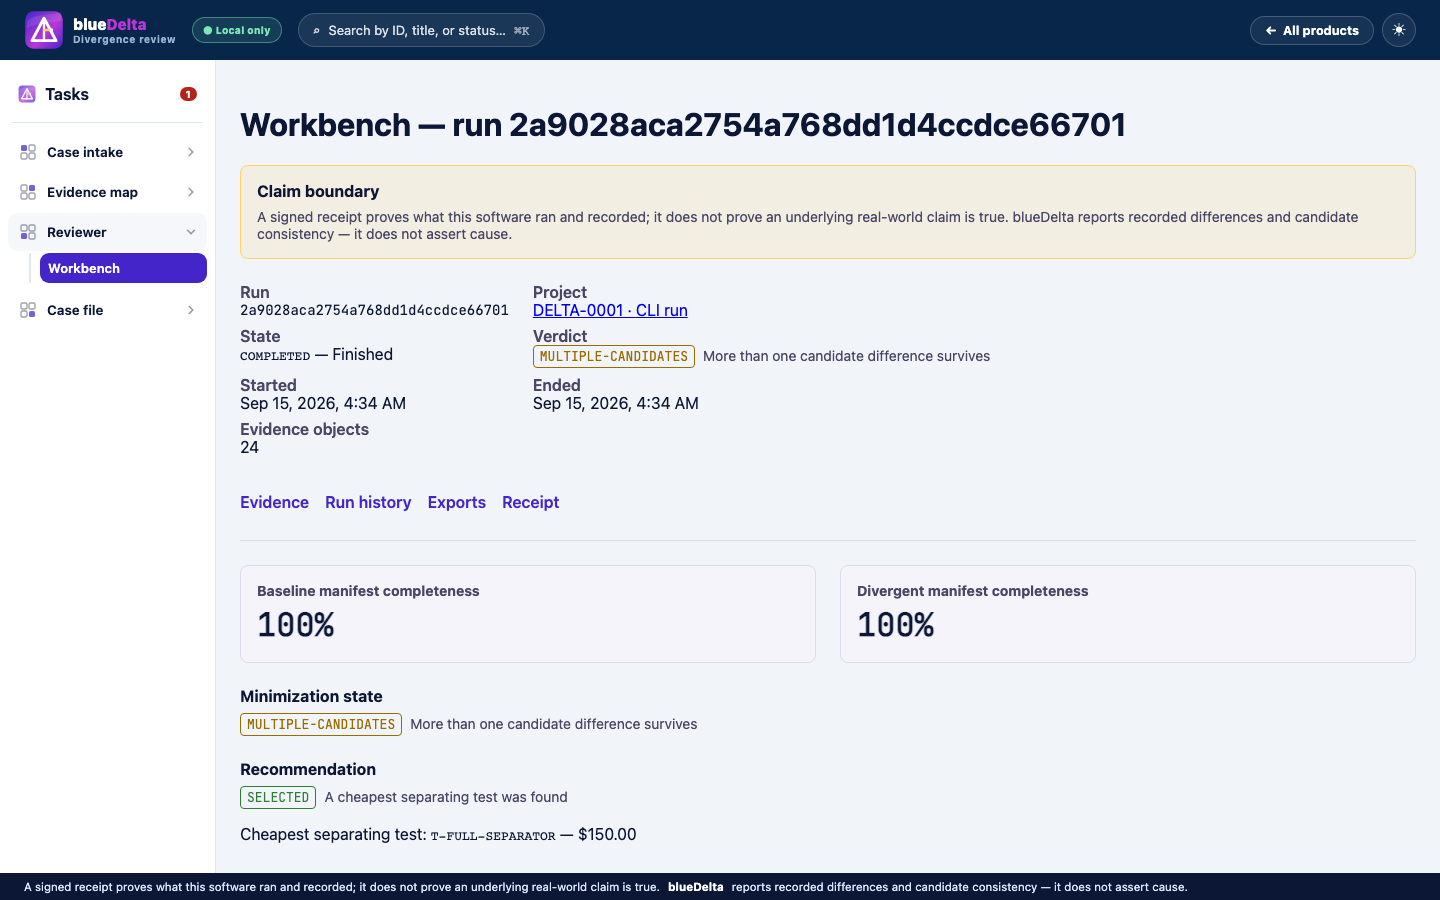
Manifest comparison — baseline vs. divergent run, with both manifests at full recorded completeness.
- Web UI exists but is not yet wired to the API (a later milestone).
- V1 core has no learned ranking by design.
Does blueDelta make the decision for me?
No. Never claims a surviving candidate caused the result, never runs an experiment or controls an instrument, and never infers from data the manifests don't contain.
Does blueDelta replace the system I already use?
No — it is an overlay. Your existing record system, LIMS, or claims platform stays exactly where it is.