blueDelta
Compares two versioned lab run manifests, excludes only the candidates ruled out by an explicit dependency rule, and — given a test catalog — recommends the cheapest experiment that would separate what's left.
Lab and research-integrity reviewers.
Never claims a surviving candidate caused the result, never runs an experiment or controls an instrument, and never infers from data the manifests don't contain.
blueDelta answers one narrow question: between a baseline run and a run that diverged, which recorded differences are still consistent with the divergence once the dependency rules have excluded the rest — and, given a test catalog, which experiment would separate the survivors most cheaply? The four screens below show the library of saved comparisons, one finished run where more than one candidate is still standing, the field-by-field evidence behind it, and the signed receipt that closes it out.

Library — every saved comparison, filterable by Draft, Active and Completed, searchable by ID, title or status. Start from files takes a baseline and a divergent run. The footer on every screen: blueDelta reports recorded differences and candidate consistency — it does not assert cause.
Open a comparison and the Workbench shows where its minimization stopped.
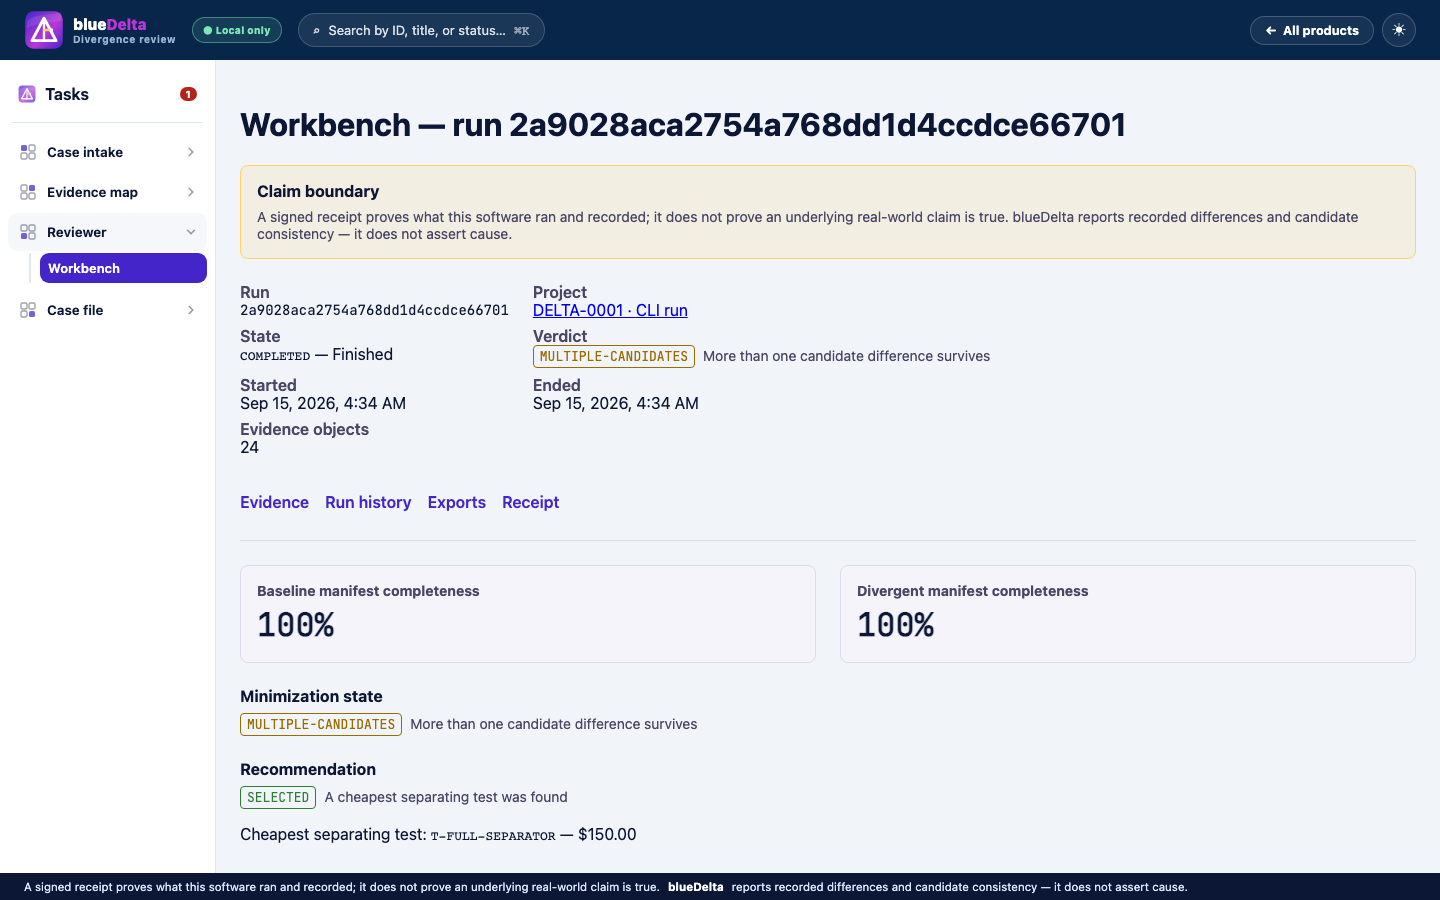
Workbench — run finished, 24 evidence objects, both manifests 100% complete against what the rules require. Minimization state MULTIPLE-CANDIDATES: more than one recorded difference survives, so blueDelta names no cause. Recommendation SELECTED: T-FULL-SEPARATOR is the cheapest catalogued test that would tell the survivors apart. The claim boundary sits above the numbers, not in a footnote.
Evidence is one click away, and shows why the workbench called it MULTIPLE-CANDIDATES; when the rules leave a single survivor the state reads SINGLE-CANDIDATE, and when the manifests cannot support the comparison it reads CANNOT-CERTIFY.
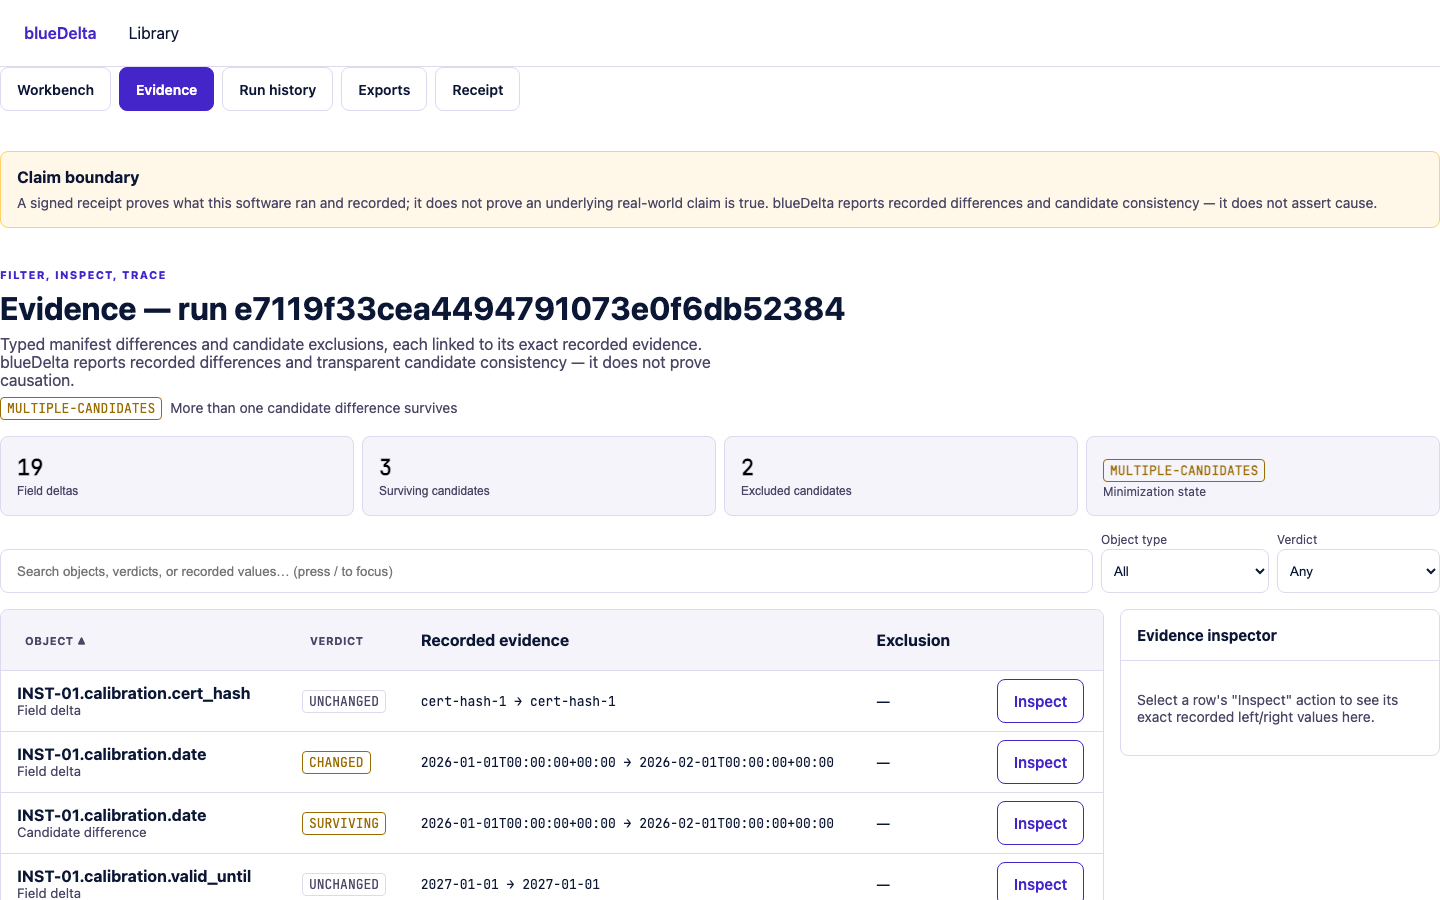
Evidence — every one of the 19 field deltas between the baseline and divergent manifests, typed UNCHANGED, CHANGED, or SURVIVING. Three surviving candidates, including a calibration date change on INST-01, are what the dependency rules could not exclude; Inspect opens the exact recorded left and right values behind any row.
Receipt is the same run's signed output.
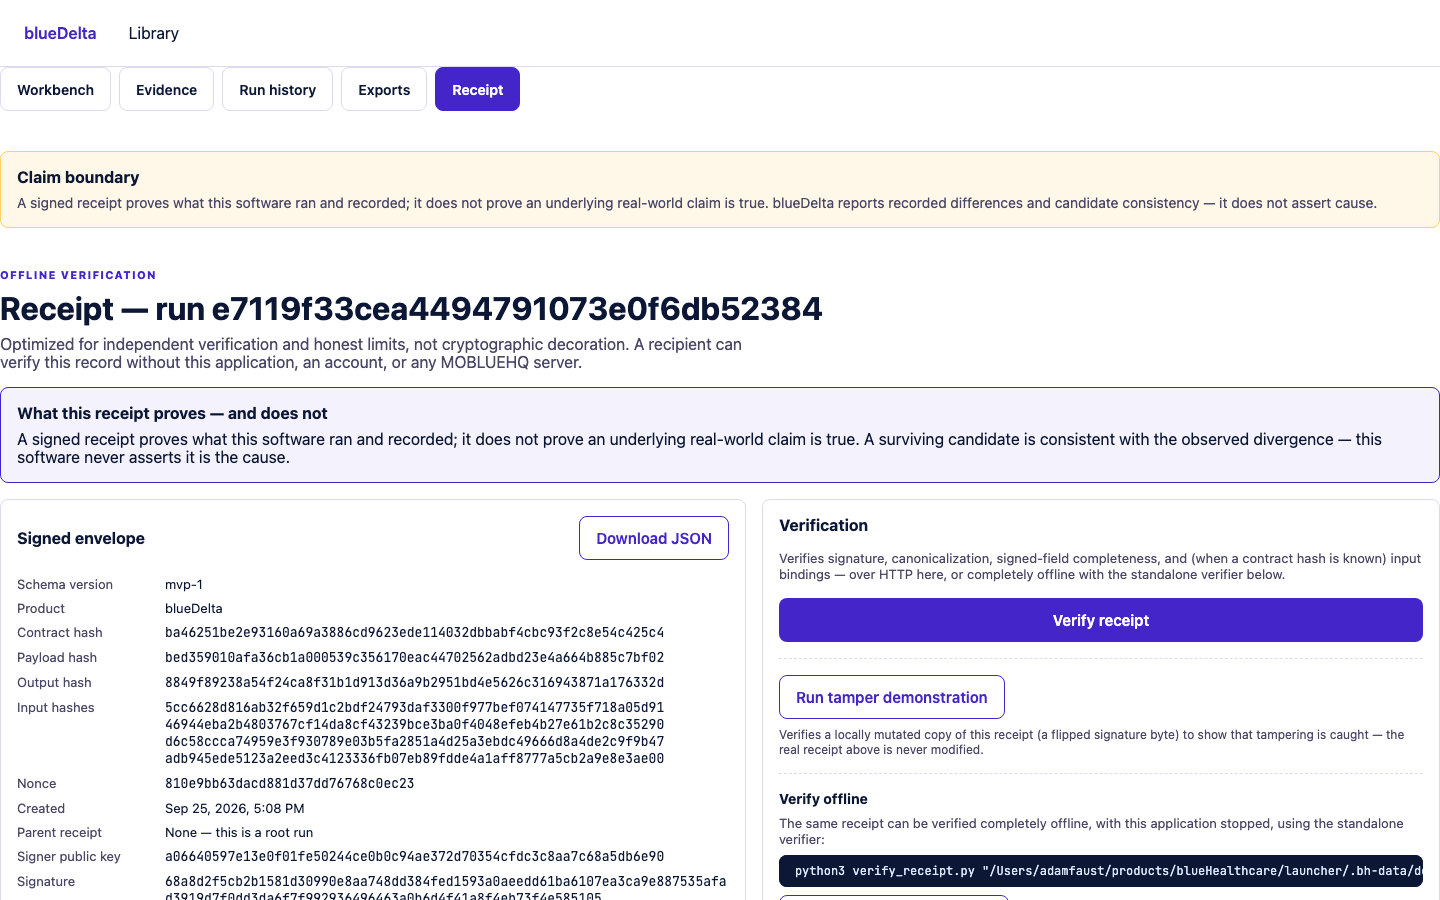
Receipt — the signed envelope for this run, with a boxed reminder above the numbers that a surviving candidate is consistent with the observed divergence, not its proven cause. Run tamper demonstration mutates a local copy to show a flipped signature byte gets caught; the offline command at the bottom performs the identical check with the application stopped.
SQLite persistence, API, and CLI landed (Milestone 6). See the status page for the measured current state.